 Vithupro Infotech
LLMOps, evaluation and private LLMs
Measure, guard and tune your LLM features, or run open models inside your own network.
The problem we solve
Most GenAI features ship without a way to tell whether the next prompt or model change made them better or worse. We add evaluation, tracing and guardrails, tune cost and latency, and, where data cannot leave your network, deploy open models on your infrastructure.
Releases by gut feel
Prompt and model changes go live because they looked fine in testing.
Costs that creep
Token spend grows faster than usage with no view of where it goes.
Data that cannot leave
Compliance rules out sending documents to a public API.
What we build
Evaluation
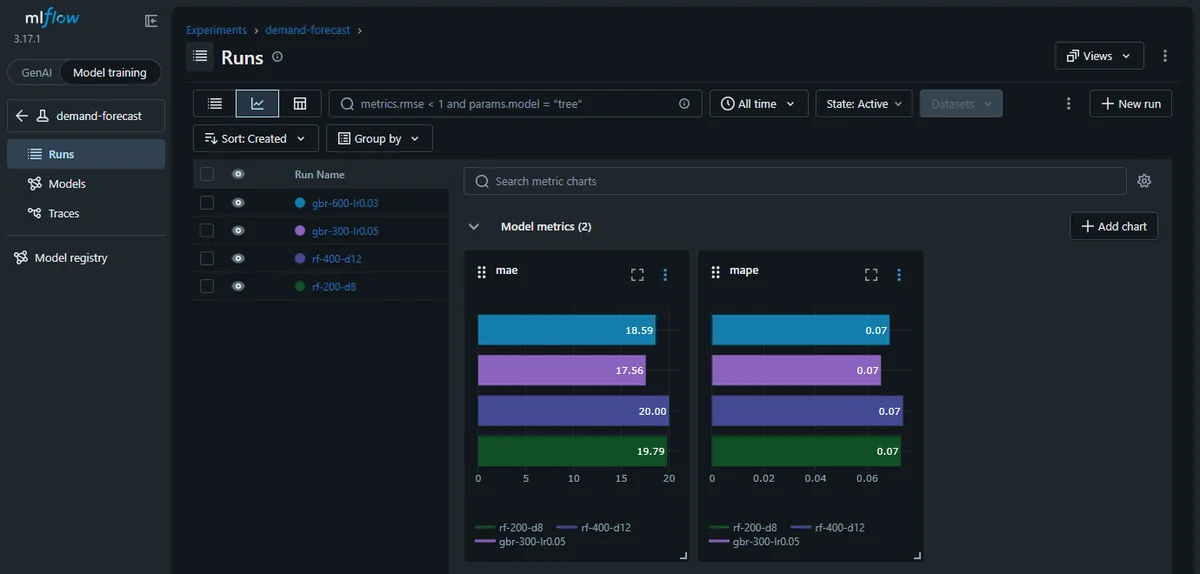
- Golden datasets built from real traffic
- Deterministic checks plus LLM-as-judge scoring
- Release gates in CI
- Online feedback loops
Guardrails and safety
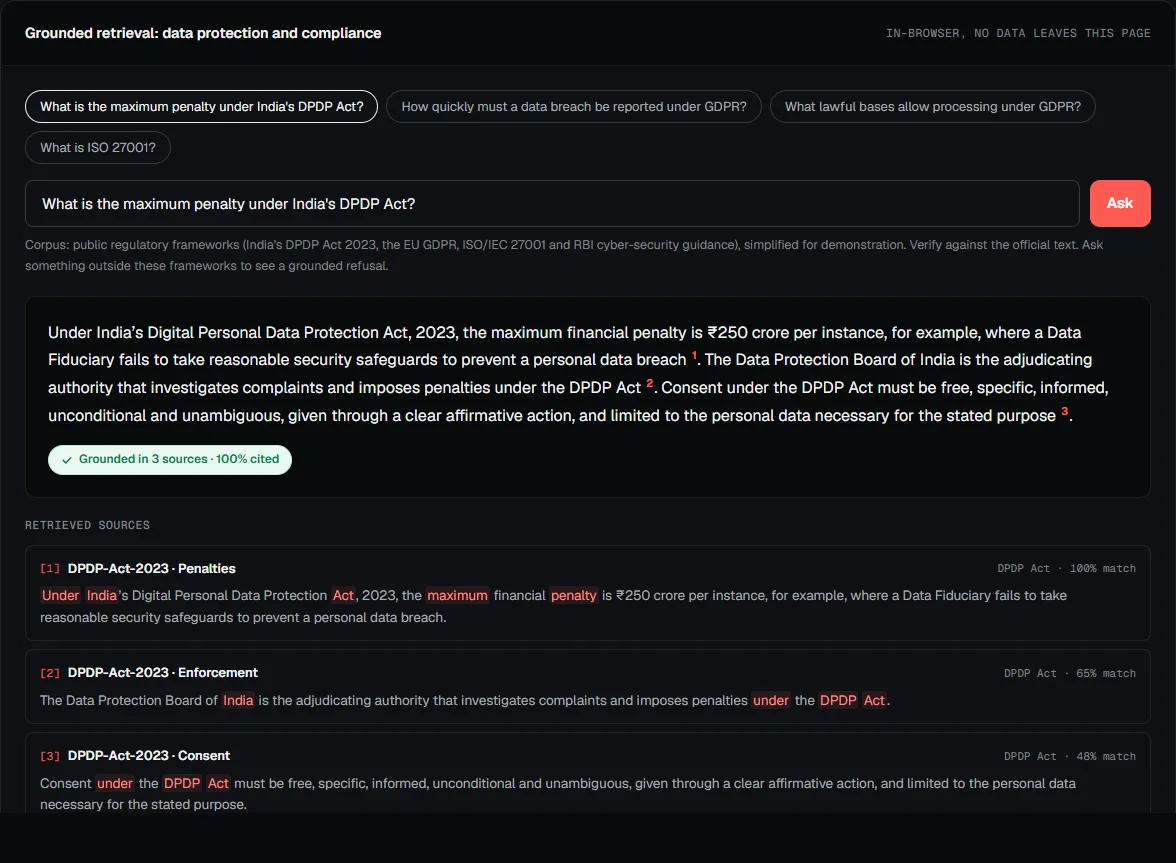
- Input and output filtering, PII redaction
- Prompt-injection defences for tools and retrieval
- Policy checks and structured output validation
- Red-team test suites
Cost and performance
- Model routing by task difficulty
- Prompt and context compression, caching
- Batching and streaming
- Per-feature cost dashboards
Private and fine-tuned models
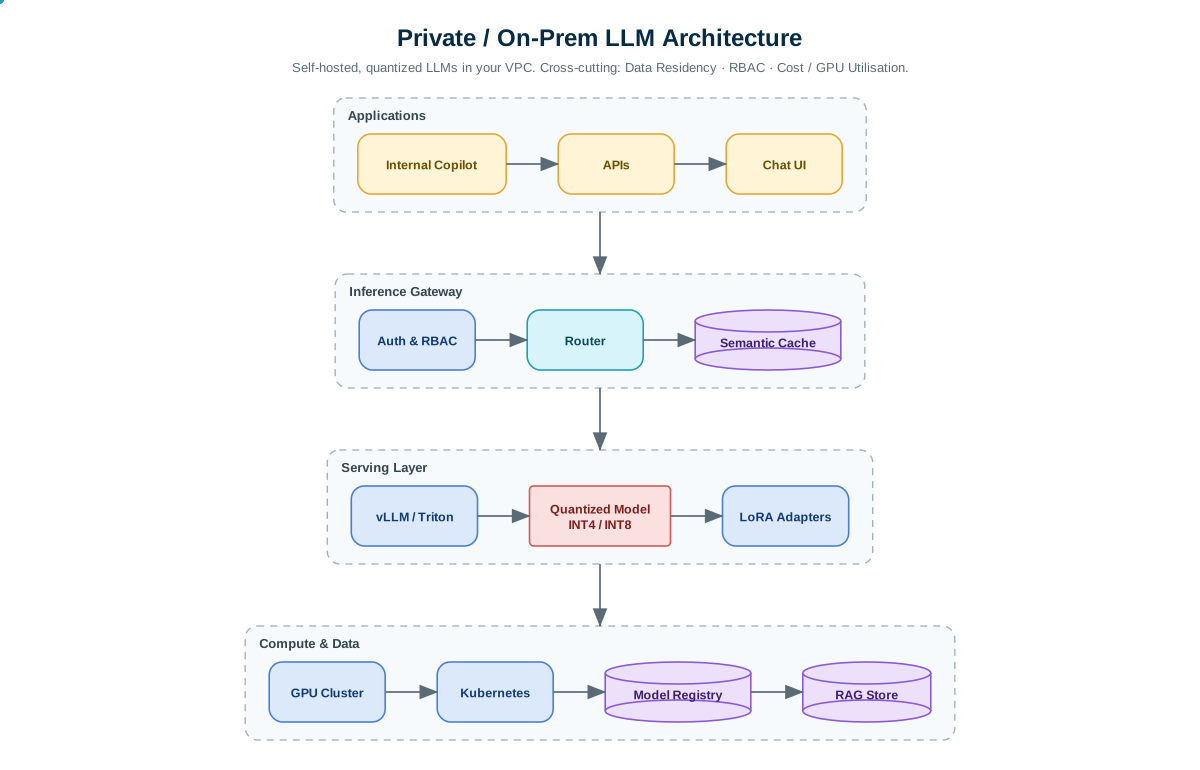
- Open models (Llama, Qwen, Mistral, Gemma) served with vLLM
- LoRA and QLoRA fine-tuning on your data
- On-premise, private cloud or air-gapped deployment
- OpenAI-compatible gateway for your apps
What this looks like when we build it
The stack
Go deeper on the tools:
How we deliver it
Eval and cost audit
1 to 2 weeks. Baseline quality, cost and latency of your current feature, with a fix list.
LLMOps setup
3 to 6 weeks. Eval harness in CI, tracing, guardrails and dashboards.
Private LLM deployment
4 to 8 weeks. Model selection, fine-tuning if needed, serving and gateway.
Questions
Is an open model good enough for our use case?
Often, yes, especially with retrieval or light fine-tuning. We test candidate models against your eval set before recommending one, so the decision is based on numbers.
What hardware does a private LLM need?
It depends on model size and traffic. We size GPU or CPU requirements from your expected load and include the numbers in the proposal.
Related services
Have an AI system to build?
Tell us what it needs to do. We reply within one business day with questions, a rough plan and the next step.
- Free 30-minute architecture call
- NDA before you share details
- You own all code and IP
- Reply within one business day