 Vithupro Infotech
Machine learning engineering and MLOps
Forecasting, prediction and vision models, shipped with tracking, retraining and monitoring from day one.
The problem we solve
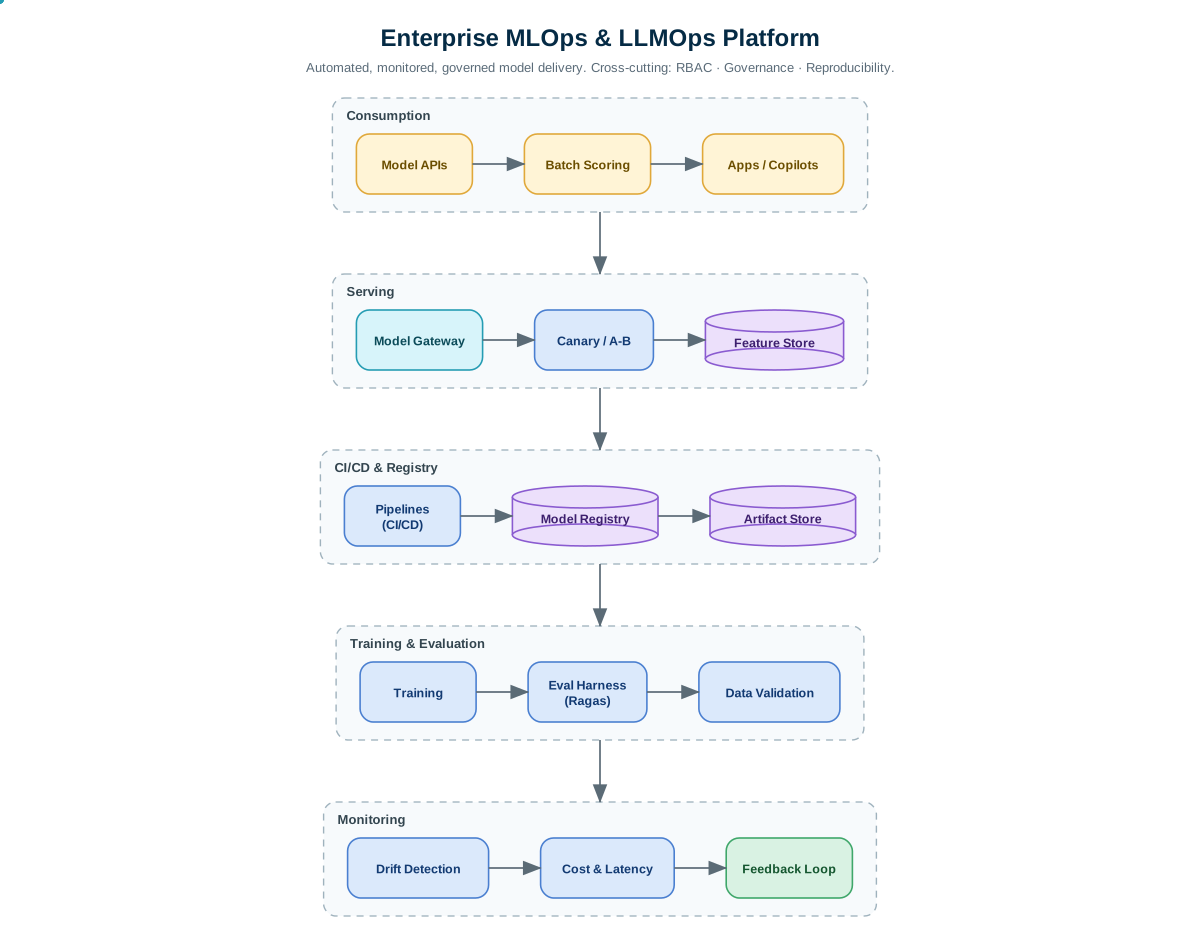
A model in a notebook is not a product. We build the model and everything that keeps it useful: reproducible training, a registry, automated retraining, serving, and monitoring that tells you when data drifts before accuracy drops.
Models that never ship
Good offline results with no path to an API or a batch job.
Silent decay
Accuracy drops as data changes and nobody notices for months.
Unreproducible results
No record of which data, code and parameters produced a model.
What we build
Models
- Demand and time-series forecasting
- Classification, scoring and churn prediction
- Recommendations and ranking
- NLP and computer vision, including edge deployment
Experiment tracking and registry
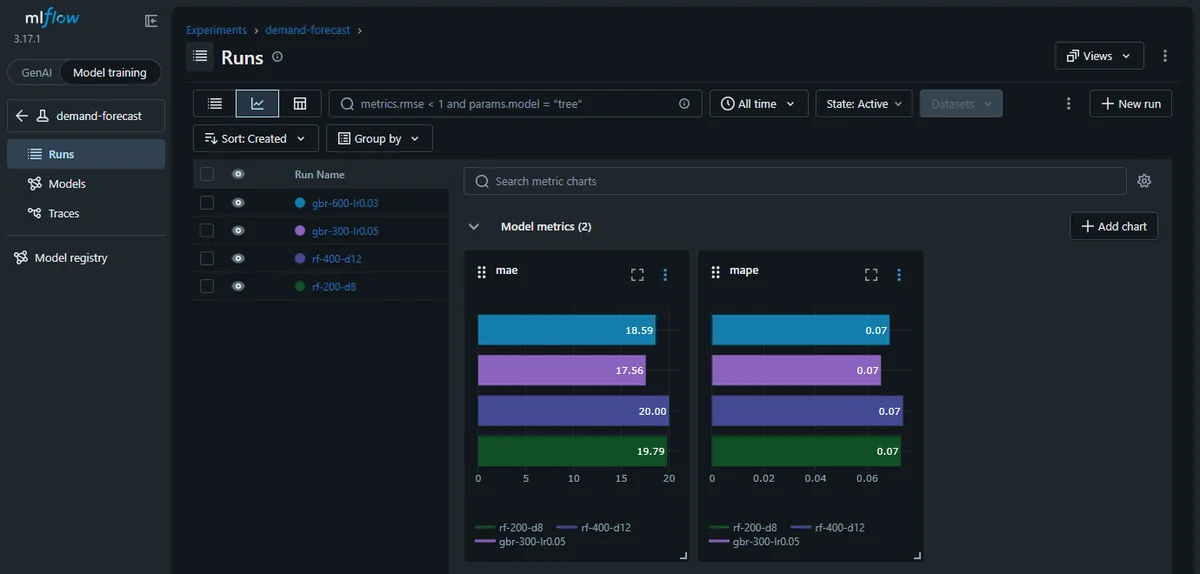
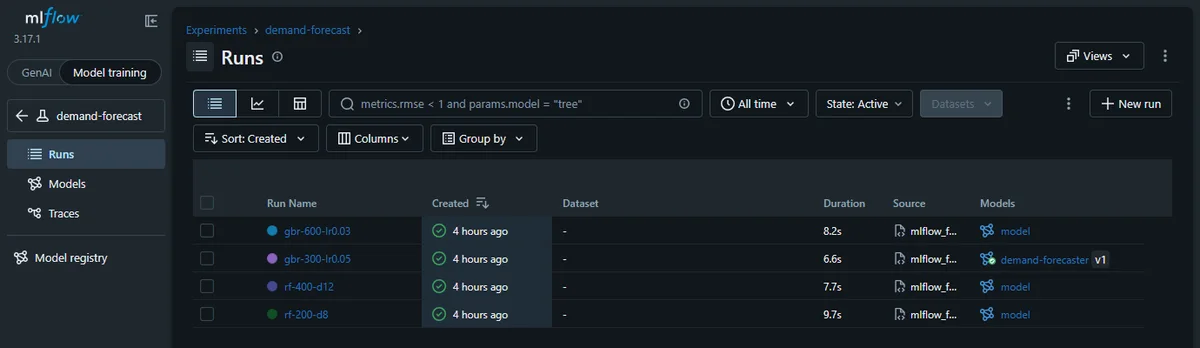
- MLflow tracking for parameters, metrics and artifacts
- Model registry with aliases and promotion rules
- Reproducible training environments
- Data versioning with DVC
Pipelines and serving
- Airflow retraining pipelines
- Batch scoring and real-time APIs
- Serving with FastAPI, BentoML, Ray Serve or KServe
- Feature pipelines and feature stores
Monitoring
- Data and prediction drift detection
- Performance tracking against ground truth
- Alerting and automated retraining triggers
- Model cards and audit trail
What this looks like when we build it
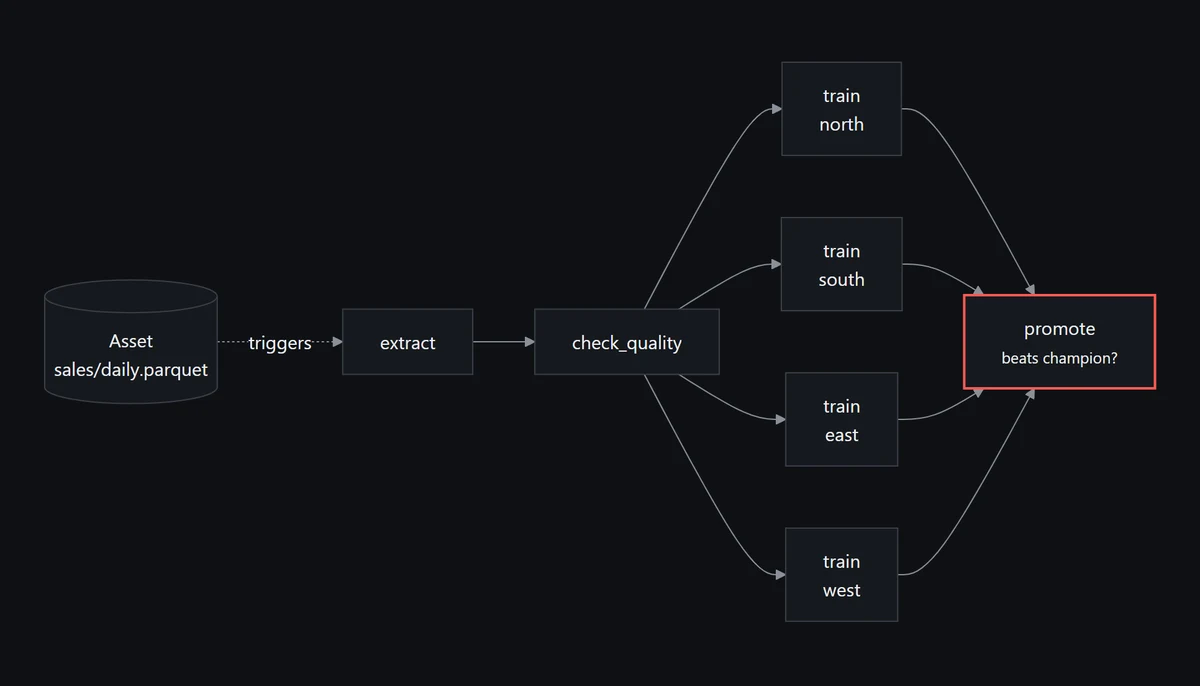
The stack
Go deeper on the tools:
How we deliver it
Model proof of concept
2 to 4 weeks. Baseline model on your data with a clear accuracy and business readout.
Production pipeline
4 to 8 weeks. Tracking, registry, retraining, serving and monitoring.
Run and improve
Monthly. Retraining, drift response and new models.
Questions
We already have a model. Can you productionise it?
Yes. We package it, add tracking and a registry, build the serving path and retraining pipeline, and set up monitoring.
Do you work on our cloud?
Yes: AWS, Google Cloud, Azure or your own servers. Everything is built in your accounts and you own the code.
Related services
Have an AI system to build?
Tell us what it needs to do. We reply within one business day with questions, a rough plan and the next step.
- Free 30-minute architecture call
- NDA before you share details
- You own all code and IP
- Reply within one business day